An early warning system, in the business sense that matters here, is AI-driven monitoring that continuously tracks market signals, competitor activity, and leading indicators to surface early threats and opportunities. The practical payoff is simple: it alerts you before lagging metrics show damage, so you can act while there’s still time. Small businesses are already using this kind of AI monitoring to catch problems early, and Blue Prysm builds that same lead time into a full strategy platform.
TL;DR:
- Anomaly detection systems require one to four weeks of historical data to reliably learn business-specific patterns and avoid false alarms.
- Static thresholds are better for hard limits like service level agreements, while anomaly detection effectively captures seasonal and dynamic metrics.
- Backtesting historical data helps ensure signals actually provide enough lead time to prevent or mitigate crises.
- False positives can be minimized by careful sensitivity, duration, and seasonality calibration, alongside tiered severity alerts.
- Regular revalidation, logging false alarms, and scope control are essential to maintain trust and effectiveness of an early warning system over time.
What an AI Early Warning System Actually Does
Most business owners find out their margin slipped, their best channel died, or a competitor undercut them when the month-end report lands. By then the damage is already booked. An AI-driven early warning system replaces that lag with continuous ingestion: it pulls data from your accounting software, CRM, ad platforms, and competitor feeds around the clock instead of waiting for a quarterly review, and it builds a baseline of what “normal” looks like for your specific business.
From that baseline, the system does four things well:
- Detects anomalies and scores how unusual a shift really is, rather than just flagging every fluctuation.
- Issues business-facing alerts, often called warning or opportunity cards, written in plain language instead of raw data.
- Traces root cause and attaches a financial-impact estimate, so you know what a 4% drop in retention actually costs you this month.
- Recommends a first action, because a warning without a next step just adds anxiety, not value.
Vendors like Miivo describe exactly this pattern: a warning that names the financial impact tends to get acted on faster than one that doesn’t. One caveat worth flagging early: if your signals touch customer-level or personally identifiable data, sector rules can apply. Telecom is the clearest example, where 47 USC §222 restricts how customer proprietary information gets used and disclosed. Know which of your data feeds carry personal information before you pipe them into any monitoring tool.
Anomaly Detection vs. Static Thresholds: Which Do You Need?
Here’s where most SMBs get it backward.
Anomaly detection solves the seasonality problem. It learns your historical pattern instead of applying one static number to every week of the year, and most systems need one to four weeks of history before the baseline is trustworthy. You tune three knobs from there:
- Sensitivity controls how far off-baseline something has to swing before it counts as unusual.
- Duration requires the deviation to hold for a set stretch of time, so a one-hour blip doesn’t trigger a page to your ops lead.
- Seasonality settings account for the fact that Tuesday traffic never looks like Saturday traffic, and neither should be flagged as abnormal.
Static thresholds still earn their place, though. If you have an SLA that says support tickets get a response within four hours, or a warehouse that physically cannot hold more than 500 units, that’s a binary state, not a pattern to learn. Anomaly detection fits dynamic, seasonal metrics; static thresholds fit hard limits, and mixing up the two is the single most common tuning mistake we see.
The other half of reliable detection is choosing the right indicator to watch in the first place. Basedash’s five-test rubric scores a candidate leading indicator on whether it’s predictive, timely, controllable, measurable, and hard to game. A SaaS team might swap “monthly churn” (lagging) for “week-two feature adoption” (leading). A sales team might swap “closed deals” for “demo-to-proposal ratio.” Before trusting any new signal, backtest it: pull your last six to twelve months of data and check whether the candidate signal actually moved ahead of the outcome by the lead time you’re expecting.
Setting Up Your Own Early Warning System: A Practical Checklist
You don’t need a data science team to stand up a working version of this in a matter of weeks. Here’s the order that actually works:
- Inventory your data sources. List every place operational reality shows up: accounting software, POS, CRM, product usage events, ad spend platforms, web analytics, and any competitor pricing or review feeds you can access.
- Prioritize by damage potential. Rank those sources by how much revenue or reputation risk sits inside them. Cash flow and customer acquisition cost usually rank higher than social mentions.
- Choose signal types per source. For metrics with enough history, use anomaly detection. For anything brand new, start with a temporary static threshold until you’ve banked enough data to learn a real baseline.
- Derive leading indicators. Walk backward from each lagging outcome you care about (churn, missed revenue target, margin compression) and pair it with one to three leading indicators that tend to move first.
- Instrument and backtest. Feed in your historical data and check whether each candidate signal would have flagged your last real crisis or windfall with useful lead time.
- Set initial sensitivity and duration, then pick delivery channels (Slack, email, a shared dashboard) and a summary cadence, whether that’s daily or weekly.
Pro Tip: Don’t wait for a perfect data pipeline before you start. Stand up static thresholds on your three riskiest metrics this week, then upgrade each one to learned anomaly detection as history accumulates. A rough early warning system beats a perfect one you never launched.
For where these alerts should actually live day to day, a well-placed dashboard beats a buried email thread every time.
Tuning Alerts So Your Team Doesn’t Tune Them Out
An early warning system that fires constantly gets ignored within a month. That’s not a hypothetical, it’s the default outcome if you skip governance.
Start with two severity tiers instead of one flat alert type. Warning-level alerts route to the team closest to the metric for investigation. Critical-level alerts push straight to an owner or executive, because they represent something that can’t wait for the next standup. Add an expiry rule too: a warning left unaddressed for a set number of hours should escalate or roll into a summary rather than keep pinging the same channel every ten minutes.
Reducing false positives comes down to the same knobs from the detection section, applied deliberately rather than left on default:
- Sensitivity tighter for critical alerts, looser for warnings you’re still calibrating.
- Lookback interval long enough to smooth out noise but short enough to catch real drift.
- Duration requirements that filter out one-off spikes.
- Seasonality adjustments so Black Friday doesn’t trip an “anomalous spike” alarm every year.
On notification strategy, batch low-urgency items into a daily or weekly summary and reserve real-time pings for anything critical. Watch for “flapping,” where a metric oscillates just above and below a threshold and fires repeated alerts for the same underlying issue. And don’t skip the operational detail almost every SMB misses: monitor the health of the detection job itself, because a silently broken data feed produces the illusion of “no news is good news.”
Pro Tip: Assign a named incident owner to every alert category before you launch, not after the first false alarm causes a fire drill. An alert with no owner is just a notification nobody’s responsible for.
From Alert to Action: What to Automate and What Needs a Human
A warning card is only as good as what happens in the next hour. Build a simple three-step playbook for every recurring alert type: a quick check to confirm it’s real, a root-cause trace to find where it started, and a corrective step with a fixed time budget, say two hours for margin drift, thirty minutes for a competitor pricing change.
Four playbooks cover most SMB scenarios:
- Margin drift alert: confirm against raw invoices, trace to input cost or discounting behavior, adjust pricing or renegotiate the affected supplier contract.
- Activation drop alert: confirm the onboarding funnel is tracking correctly, trace to a recent product or checkout change, roll back or patch the friction point.
- Competitor pricing change: confirm the source is accurate, check whether it’s a permanent shift or a promotion, decide whether to match, hold, or reposition.
- Supplier cost spike: confirm the invoice isn’t a billing error, trace to market conditions or contract terms, escalate to renegotiation if the spike is structural.
Reversible, low-risk actions, like sending an automatic internal Slack summary or pausing an underperforming ad set, can run without a human in the loop, ideally with a throttle that caps how often the automation fires. Anything touching pricing, customer communication, or supplier relationships needs a human sign-off. Once you resolve an alert, feed the outcome back into your indicator list. If a leading indicator didn’t actually predict the outcome, drop it or reweight it. Building that threat analysis workflow into a repeatable habit is what separates teams that improve their detection over time from teams stuck re-litigating the same false alarm every quarter.
Early Warning Systems Look Different by Domain
The core mechanic, watch a baseline, flag deviation, alert with lead time, shows up everywhere, but the specifics shift hard by industry, and it’s worth knowing the neighboring use cases so you don’t confuse them with the business version covered here.
Environmental and disaster-response systems monitor seismic, weather, or flood sensor data to warn communities and emergency managers ahead of physical hazards. Industrial systems watch equipment vibration, temperature, and throughput to catch mechanical failure before a production line goes down. Financial-sector systems, distinct from small-business monitoring, track transaction patterns and market volatility to flag fraud or systemic risk at scale. Cybersecurity systems monitor network traffic and login behavior to catch intrusions before data leaves the building.
What all four share with the SMB strategy version is the same underlying discipline: a learned baseline, a threshold for “unusual,” and a lead-time gap between detection and consequence. What differs is the source data and the cost of a false negative. A missed industrial vibration anomaly can mean a shutdown; a missed SMB margin anomaly means a bad quarter, not a plant closure. That difference is exactly why threat-detection systems built for factories or networks don’t transfer cleanly to a 20-person business tracking customer acquisition cost and competitor pricing. The math, the data volume, and the stakes are all different, which is why a strategy-specific monitoring layer, tuned to business signals rather than sensor data, tends to outperform a repurposed industrial or security tool for this job.
Where Machine Learning Actually Improves Accuracy
Machine learning earns its place in an early warning system by handling pattern complexity that a static rule simply can’t. A rule-based system might say “flag if conversion rate drops below 2%.” A model-based system learns that your conversion rate naturally dips every Monday and spikes every payday, and only flags deviations from that learned pattern, which is why anomaly detection models cut false alarms compared to fixed thresholds in metrics with real seasonal texture.
The adaptability piece matters as much as the accuracy piece. That’s the difference between a tool that gets more useful over time and one you have to keep manually recalibrating.
Where machine learning adds real value beyond basic anomaly flagging is signal scoring and root-cause suggestion. Instead of a flat list of every metric that moved, a scored system ranks alerts by how unusual and how financially significant they are, so your team’s attention goes to the three things that matter, not the fifteen that technically deviated. This is also where the technology has real limits worth naming honestly: a model is only as good as the pattern it was trained on, and a genuinely novel event, a supply shock nobody’s seen before, a brand-new competitor tactic, won’t get caught by pattern recognition alone. That’s a case where human judgment and a static rule still belong in the loop, not a case where the model failed.
Where Early Warning Systems Fall Short
No monitoring system, AI-driven or not, is immune to bad inputs. The most common failure mode isn’t a broken algorithm, it’s a broken data feed feeding a perfectly good one.
Data quality is the first crack. If your CRM has duplicate contacts, your POS system logs refunds inconsistently, or your ad platform’s attribution window doesn’t match your actual sales cycle, the baseline the system learns is wrong from day one, and every alert built on it inherits that error. Garbage in doesn’t just mean garbage out here, it means false confidence in a number that was never right.
Latency is the second crack, and it’s sneakier. A system that ingests data once a day can’t give you same-day lead time no matter how good its anomaly detection is. If your competitor drops a price at 9 AM and your feed only updates overnight, you’ve lost half a day of reaction time to a pipeline delay, not a detection failure.
Silent job failure rounds out the trio. An anomaly-detection job can stop running, a datafeed can disconnect, or a model can hit a memory limit, and if nobody’s watching the health of the detection system itself, you get the worst possible outcome: total silence that looks exactly like “everything’s fine.” That’s why monitoring the detection job’s own health, datafeed status, model memory, last-run timestamp, isn’t optional infrastructure hygiene. It’s the difference between a system that fails loudly and one that fails invisibly for three weeks before anyone notices the warnings stopped coming.
How to Know If Your Early Warning System Is Actually Working
The honest test of any early warning system isn’t whether it generates alerts, it’s whether those alerts would have caught your last real crisis with enough lead time to change the outcome.
Backtesting is the core method. Pull your last six to twelve months of data, run your candidate indicators and thresholds against it, and check two things: did the signal flag before the outcome hit, and by how much lead time. A leading indicator that only shows up the same week as the lagging outcome isn’t leading anything, it’s just a second lagging metric with extra steps.
Precision and recall are the two numbers worth tracking once the system is live. Precision asks: of the alerts that fired, how many represented a real, actionable issue? Recall asks: of the real issues that happened, how many did the system actually catch? A system tuned only for high recall will flood your team with noise; one tuned only for high precision will miss real problems by staying too quiet. The right balance depends on the cost of a false negative in that specific metric, a missed churn signal usually costs more than an unnecessary Slack ping, so it’s fine to accept more false positives there.
The other validation layer is simpler and often skipped: track how often an alert actually led to a corrective action, and how often that action worked. If your margin-drift alerts fire monthly but nobody ever changes pricing in response, the alert isn’t broken, but your playbook is. Effectiveness isn’t just detection accuracy, it’s the full loop from signal to action to measured outcome, and any of the three legs can be the weak one.
What Successful Early Warning Systems Look Like in Practice
The clearest pattern across working implementations isn’t the sophistication of the model, it’s the specificity of the output. Vendors like Miivo report that alerts attaching a dollar figure and a recommended first action get acted on far more consistently than a bare notification saying a number moved. A warning that just says “CAC anomaly detected” gets a shrug and a “we’ll look at it later” that often never comes.
A second pattern shows up in how the best-run teams treat false alarms, not as a nuisance to tolerate, but as data to act on. Every false positive gets logged, and the sensitivity or duration setting on that specific alert gets adjusted within the week rather than left to keep crying wolf. Teams that skip this step end up training their own staff to ignore the system within a quarter, which defeats the entire purpose of building it.
The third pattern is scope discipline. The implementations that hold up over time don’t try to monitor everything at once. They start with three to five metrics that map directly to revenue or retention risk, prove the system catches something real within the first month, and only then expand coverage. Trying to instrument forty signals on day one produces exactly the kind of alert fatigue that gets the whole system muted six weeks in.
Why the “Set It and Forget It” Myth Is the Real Risk
Every early warning system pitch promises the same thing: catch problems before they cost you. Run that promise through a basic scrutiny check and most of it holds up, monitoring genuinely beats monthly hindsight. But the part vendors gloss over is that a system tuned once at launch and never revisited degrades quietly. Your business changes. Seasonality shifts. A leading indicator that predicted churn last year can lose its predictive power the moment your customer base or pricing model changes underneath it.
What actually separates a useful early warning system from an ignored one isn’t the AI model, it’s the discipline of periodic revalidation, the backtesting habit, the false-positive log, the willingness to retire an indicator that stopped earning its place on the dashboard. That’s less exciting than “AI catches problems before they happen,” but it’s the part that determines whether your team trusts the alerts six months from now or has quietly muted the channel.
Blue Prysm’s approach leans into that discipline rather than around it, pairing continuous competitor tracking with strategy frameworks so a warning card connects to an actual next move, not just a number. The checklist in this article, source inventory, baseline, backtest, tune, revalidate, is the same discipline behind how Blue Prysm’s briefings and decision-making tools get built for SMB teams who don’t have a data science department to lean on.
— Colin Bowdery
Get Lead Time Instead of Hindsight
Everything covered here, anomaly detection, leading indicators, severity tiers, playbooks, is the groundwork of a working early warning system. Building all of it from scratch with spreadsheets and manual checks is possible, but it eats the exact time you’re trying to save. Blue Prysm’s Market Analysis Platform does the continuous monitoring and baseline-building described above, then routes what it finds into warning and opportunity cards tied to your actual strategy, not a generic dashboard you still have to interpret alone.
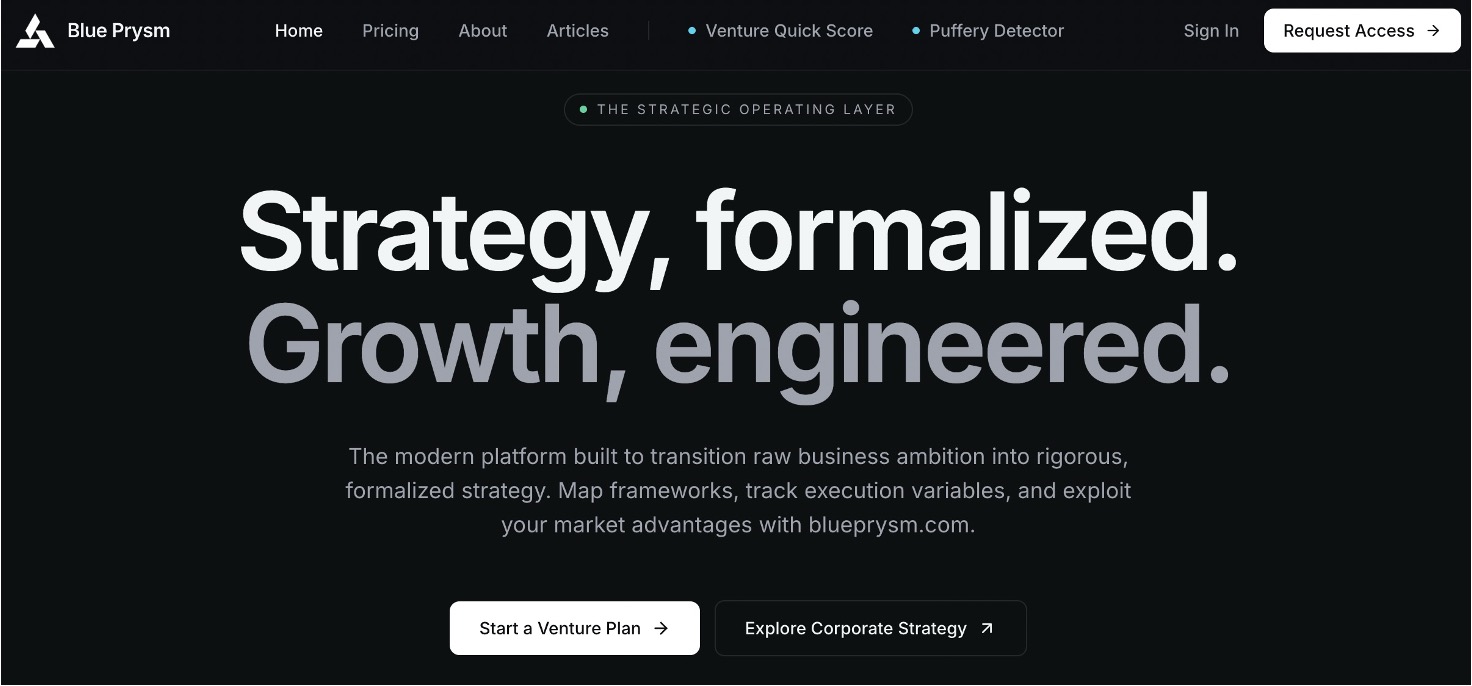
Where this goes further than a standalone alert tool is the connection to action. An alert that flags rising customer acquisition cost is more useful next to a strategy framework that tells you what to do about it, and a competitor price drop means more when it’s tracked against your own positioning rather than sitting in isolation. If you want to see what an alert actually looks like before you commit to anything, look at a sample intelligence briefing to see the format and the recommended first action attached to a real scenario. From there, the next step is straightforward: set up your first three monitored metrics and see what surfaces in the first two weeks.
Sources
- How small businesses are using AI as an early warning system — Forbes
- Anomaly detection — New Relic docs
- Leading vs lagging indicators — Basedash blog
- Configuring anomaly detection alerts — Elastic documentation
- 47 USC §222 — Privacy of customer information (U.S. Code)
FAQ
What Is an Early Warning System in Business?
It’s AI-driven monitoring that continuously tracks metrics, competitor moves, and leading indicators, then alerts you when something deviates from its learned baseline, before lagging reports would show the damage.
How Is Anomaly Detection Different From a Fixed Threshold?
Anomaly detection learns your historical pattern and adjusts for seasonality, while a fixed threshold applies one static number regardless of context, which makes it better suited to hard limits like SLAs.
How Many Leading Indicators Should I Track Per Metric?
Pair each lagging outcome with one to three leading indicators that pass a predictiveness and controllability test, rather than tracking everything measurable.
How Do I Reduce False Positives in My Alerts?
Adjust sensitivity, duration, and seasonality settings gradually based on a logged history of false alarms, and give any new anomaly-detection signal one to four weeks of history before tuning it aggressively.
Does Blue Prysm Offer This Kind of Monitoring?
Yes. Blue Prysm’s Market Analysis Platform monitors market and competitor signals continuously and delivers business-facing alerts tied to strategy recommendations, rather than raw data you have to interpret yourself.